
Data Prep Agent: Turn Raw Files into Query-ready Tables

Clean data is worth more than messy data. It can power a dashboard, an API, or another team’s pipeline.
Getting there, however, takes a data engineer: resolving duplicates, fixing inconsistent values, and structuring data for future questions. Paid once upfront, this tax makes every subsequent analysis faster and cheaper. But data engineers rarely have the time to do this for every data source, so the queue keeps growing as more data sits untouched in an S3 bucket or export folders, in whatever shape it arrived.
AI agents can change the economics of this labor-intensive data engineering. For example, you can point an agent directly at a folder of messy files. But because the data is unstructured, it will re-derive the data engineering from scratch every time, causing a big latency hit. More concerning, the same question asked on two different days can lead to different answers, which makes the answers hard to trust.
The Setup-Analysis Tradeoff
Previously, getting your own data into Manifold involved the two extremes of the tradeoff curve. The easier an option was to set up, the harder the downstream analysis became.
Turn Raw Files into Query-ready Tables in the Same Conversation
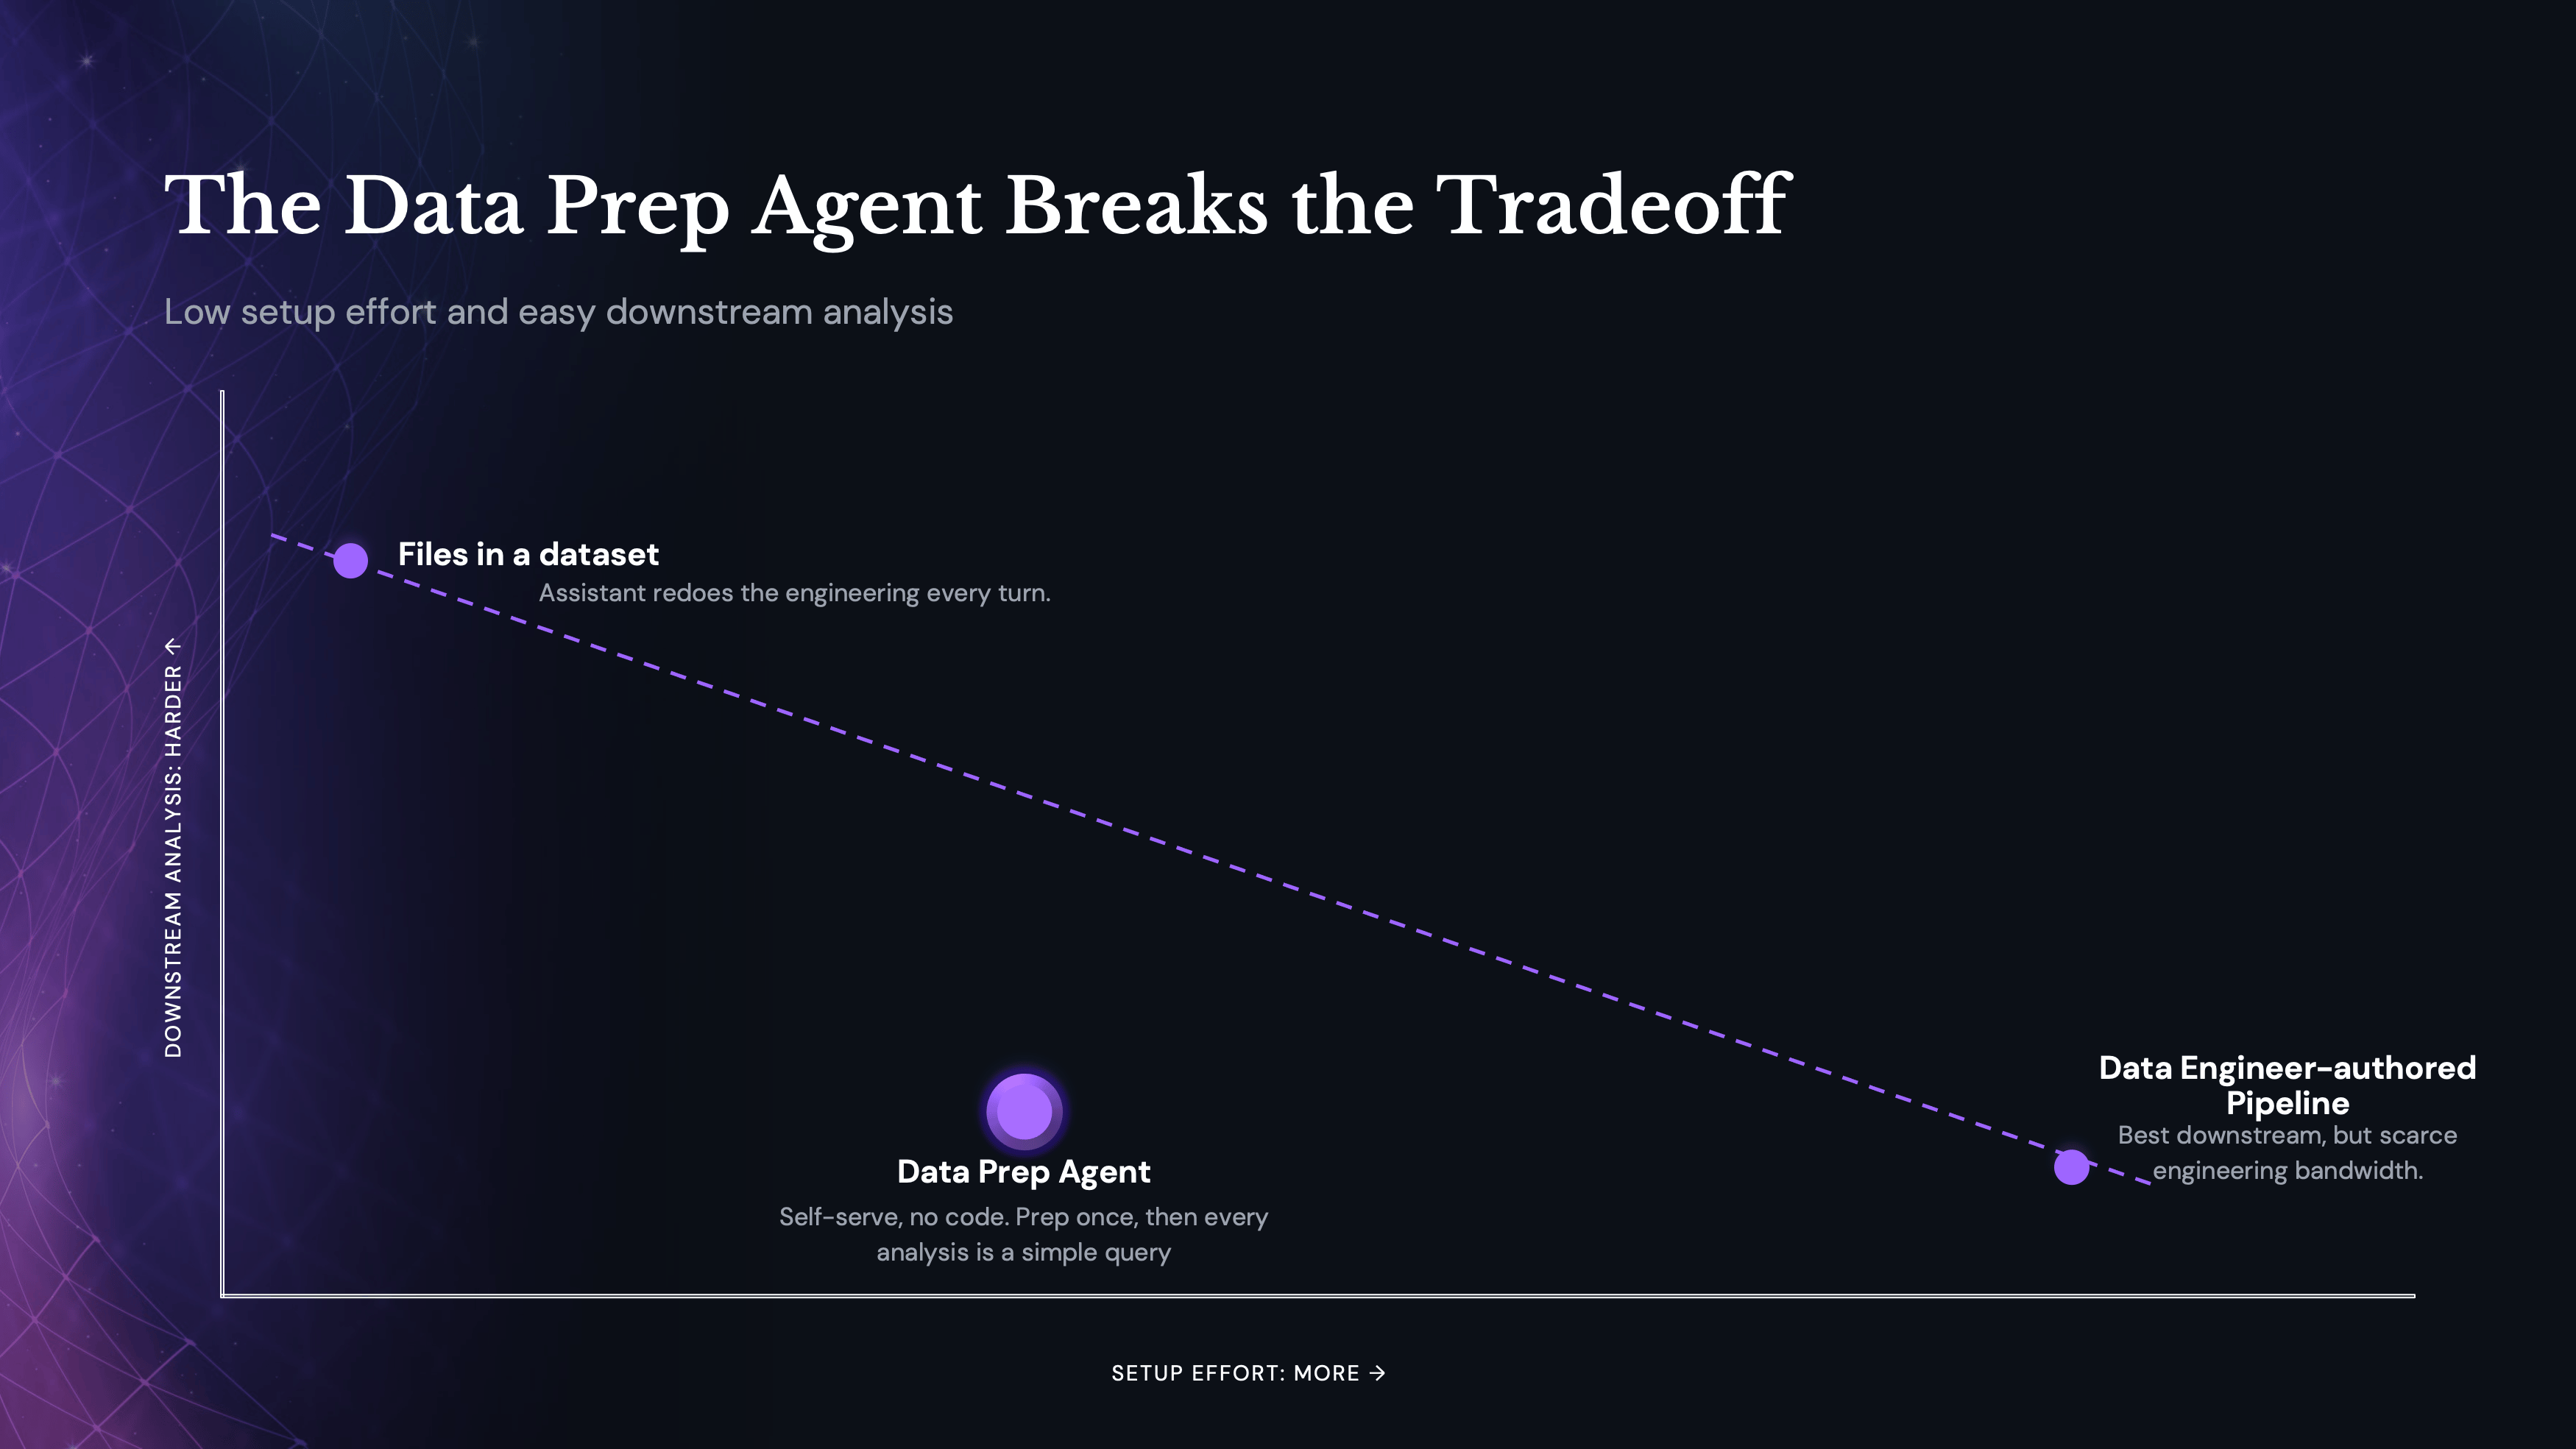
Enter Data Prep Agent. It’s a new agent that walks the same sequence as a careful data engineer but makes that experience available to a much larger set of users. It transforms messy source data into clean, typed tables in Snowflake that are optimized for downstream query patterns.
- Profile: inventories the files you've staged and flags data smells: row and column counts, likely keys, whether a file is flat or nested and needs reshaping first.
- Plan: interviews you about layout, types, and keys, and writes the plan down for you to approve before it changes anything.
- Transform: runs the Python code to perform prerequisite tasks for building the clean file—unpacking a nested JSON, flattening a VCF—before the data lands. It saves the transformation code beside the data, so it's inspectable and re-runnable rather than something that happened once inside a chat.
- Ingest: loads the result into the dataset's own database schema.
- SQL Transformation: turns SQL queries into real tables end-to-end that can be queried and refined before publishing into the shared dataset.
- Verify: sniff-tests the loaded table against the profile and any checks you prioritize.
- Contextualize: ensures Manifold's agents have grounded context on how to query the dataset and sets up limited-preview access so the dataset is explorable immediately.
What used to take a ticket, a queue, and a multi-step build now happens in a single conversation with Data Prep Agent.
Built for Everyone on the Team
Here’s the good news: you don’t need to know data engineering to work with Data Prep Agent. All you need to know is your data and what you want to ask of it.
We’ve encoded years of experience structuring common biomedical file formats—VCF genotype files, RNA-seq count matrices, and copy number variant calls—into Data Prep Agent. The agent identifies the data type during profiling and recommends mapping it to a known-good schema instead of designing one from scratch. At genomic scale, this is the difference between a query that returns in seconds and one that never finishes because it’s stuck in a constant cycle of re-engineering the data setup.
What this means is that an independent researcher can prep their lab's data once, so nobody on the team redoes the same cleanup for the umpteenth time. A data provider can prep their real-world data before licensing it out, so every customer who receives it gets the same clean tables instead of their own interpretation of the raw files.
This frees data engineers from tedious, manual work so they can focus on the problems that actually need a human: production pipelines into source systems, hard harmonization across systems, and integration work no agent can shortcut.
What Changes for You Today with Data Prep Agent
- The cost of parsing messy data moves from every analysis to a single ingest, done once.
- Teams onboard their own flat files in plain-language conversations, with no engineer in the loop.
- The transform code and verification checks persist beside the data, so the next person to touch the dataset can see exactly what happened to it.
- Because the output is a real table, it carries through every path on Manifold: other agents, notebooks, and workflows.
Get Started with Data Prep Agent
Data Prep Agent is live today on Manifold. If you have messy files you've been putting off ingesting, whatever shape they're in, talk to your Manifold account manager about turning on Data Prep Agent for your team.
FAQ
What is Data Prep Agent?
Data Prep Agent is Manifold's self-serve agent that turns messy files into clean, query-ready tables in your Snowflake without needing code or data engineering.
What file formats does Data Prep Agent support?
CSV, JSON, TXT, and biomedical formats like VCF, RNA-seq count matrices, and copy number variant calls. Non-tabular and nested files get transformed right in the conversation before they land.
Do I need a data engineer to use it?
No. You need to know your data and what you want to ask of it. The agent handles profiling, planning, transforming, and loading.
Where does my data end up?
In your own dataset's schema in your own Snowflake as a clean, typed, queryable table.
Does it change who owns or can access my data?
No. The agent acts under your own identity, so ownership and access controls stay exactly what they'd be if you'd loaded the table yourself.
